
The conversation about AI coding assistants tends to focus on code quality, is the generated code correct, is it secure, is it maintainable. That is a legitimate concern, but it misses a second, quieter risk that has nothing to do with the code the agent writes and everything to do with what the agent can see and do.
An AI coding agent is not just a text generator. It is a process running on a developer’s machine with access to that machine’s files, often access to cloud credentials, and a habit of sending whatever context it gathers to an external large language model. That combination makes every coding agent an identity and data-exfiltration surface, whether or not it ever writes a single insecure line.
What the Agent Can Actually See
To be useful, a coding agent reads context. When a developer asks it to “fix the deployment script” or “figure out why this API call fails,” the agent pulls in the surrounding files to understand the problem. That surrounding context routinely includes things that were never meant to leave the machine:
.envfiles with API keys and connection strings.- Cloud credential files such as
~/.aws/credentials. - Private keys, certificates, and
kubeconfigfiles. - Configuration with production values.
- Source and documentation that may contain real customer data or personal information.
The developer does not deliberately hand these to the agent. The agent gathers them as context because that is how it produces a useful answer. And then that context gets sent onward.
The Exfiltration Path Nobody Sees
Here is the part that makes this an identity and data risk rather than just a privacy footnote: the context the agent gathers is transmitted to the LLM provider’s API to generate a response. Every prompt that includes a secret is a secret leaving your environment for a third party. Every prompt that touches a file with personal data is that data being transmitted outside your control.
There is typically no built-in mechanism in the agent to prevent this, no default that says “do not include credential files in the prompt.” The developer does not see it happening; the transmission is invisible in the normal flow of asking the agent for help. The security risks of Copilot, Cursor, and Claude Code share this exact shape. And a security team watching network egress sees encrypted traffic to a legitimate AI provider, which looks entirely normal. The exfiltration hides inside expected behaviour.
The Credential Problem: Agents With Standing Access
Beyond what the agent reads, there is what the agent can do. To perform real work, fix an S3 policy, query a database, deploy a change, an agent needs credentials to act on cloud resources. The common approach is to give it long-lived credentials stored in the developer’s local environment.
That decision quietly turns the agent into a powerful identity:
- The blast radius is the credential’s full scope, not the task’s. An agent given a developer’s AWS keys can do anything those keys allow, indefinitely, regardless of how small the actual task was.
- The credentials persist. Long-lived keys in a dotfile outlive the task, the session, and often the developer’s memory that they exist. They sit on a machine that could be lost, compromised, or misconfigured.
- The attribution is muddy. When an agent acts with a developer’s standing credentials, distinguishing the human’s actions from the agent’s, or an attacker’s, after the fact becomes difficult.
An AI agent with long-lived production credentials is not a convenience feature; it is a credential incident waiting for a trigger.
Why Scale Makes It Worse
Every risk above exists for a single developer with a single agent. Now multiply. When an organisation rolls AI coding agents out to a whole development team, each developer is an instance of the same exposure, each machine holding credentials, each prompt a potential exfiltration event. The probability that at least one credential leaks or one piece of sensitive data escapes stops being a question of “if” and becomes a question of “when.” Scale does not add the risk linearly; it makes an eventual incident close to certain without controls.
How to Think About the Controls
You do not solve this by banning AI coding agents; that ship has largely sailed, and the productivity gains are real. You solve it by treating the agent as what it is, an identity and a data-egress point, and applying controls accordingly.
On the data side: something needs to inspect what the agent is about to send before it leaves the machine, and stop secrets and sensitive data from being included. This is the job of a coding agent guardrail. The control has to sit between the agent and the LLM, on the developer’s device, because that is the only point where you can catch a secret before it is transmitted — the same egress problem that makes MCP server security worth understanding when agents connect to external tool-servers.
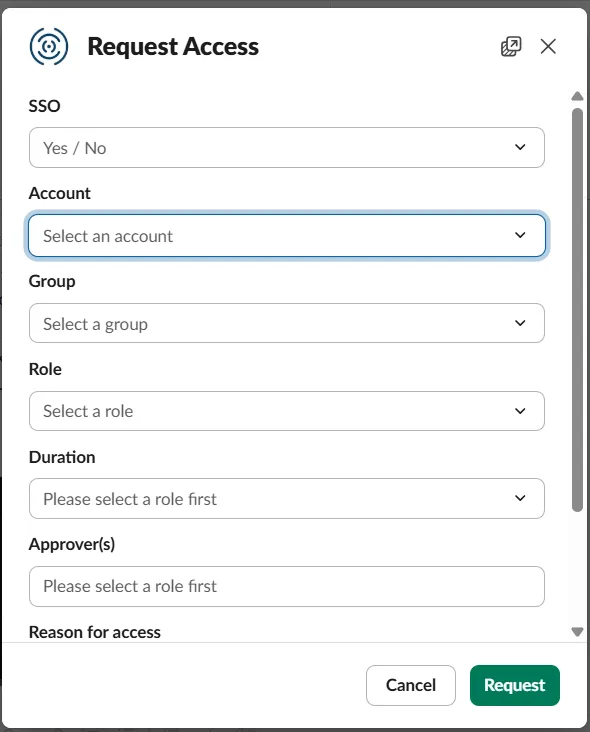
On the credential side: the agent should not hold long-lived keys at all. The better model is just-in-time access for the agent as a non-human identity — via Coding Agent JIT, an agent requests access to a specific resource for a specific action for a bounded time, that access is granted (with human approval for sensitive operations), and it revokes automatically when the task is done. No standing credentials in dotfiles. It is the same pattern used for JIT on Jenkins pipelines and other non-human identities. The blast radius collapses from “everything the key allows, forever” to “this one action, for a few minutes.”
On the visibility side: you cannot govern agents you cannot see. Knowing which agents are running, on which machines, with what access, is the baseline any governance effort requires. Shadow adoption, developers individually installing agents nobody approved, is common and needs to be discoverable. Bringing all of this under one program is what securing AI coding agents at scale for enterprise development teams covers end to end.
The Bottom Line
The security question about AI coding agents is not only “is the code any good?” It is “what can this agent see, what can it send, and what can it do?” An agent reads your secrets as context, transmits that context to a third party, and often carries standing credentials to your cloud. Treat it as a first-class identity and a data-egress point, control what it can transmit and what it can access, and the productivity of AI-assisted development stops being a security liability.
People Also Read
- Copilot, Cursor & Claude Code Security Risks: What Teams Miss
- The AI Coding Agent Attack Surface: The Cursor/Aurora Breach
- What is IAM Just-In-Time (JIT) Access?
- Is AI-Generated Code Safe to Ship? What to Check Before It Reaches Production
- Why IAM in the Cloud Needs Attention
- AI Code Security: The Real Problem













